The Technical Architecture of AI-Driven Simulation
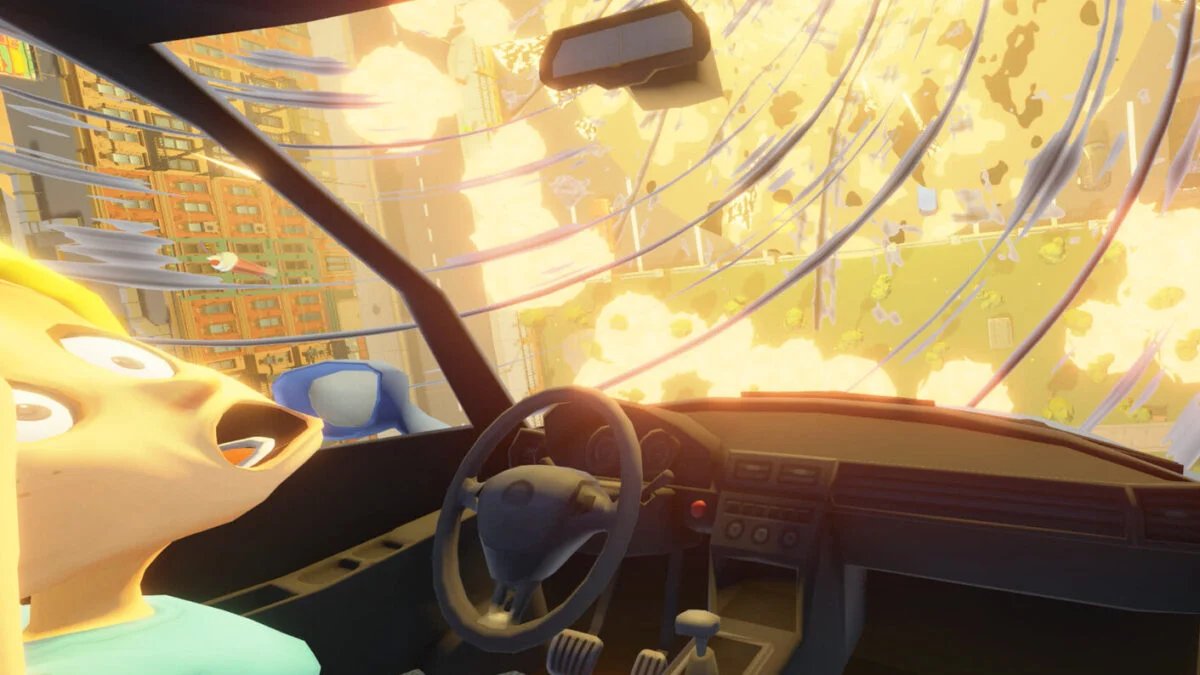
The upcoming title Teach My Little Sister How To Drive, developed by the independent studio Easy Fox, represents a technical departure from traditional scripting in simulation gaming. Unlike standard games where character responses are limited to pre-written dialogue trees or fixed branching paths, this project utilizes Large Language Models (LLMs) to power the titular character. The core functionality relies on a live chat interface where the player serves as an instructor, providing verbal guidance to a digital student navigating a virtual driving course.
From a development standpoint, the game functions as a wrapper for high-level AI services. Each interaction between the player and the in-game character sends a packet of data—the user’s instructions—to an external server, such as Google Gemini or OpenAI’s GPT models. These servers process the natural language, analyze the context of the driving scenario, and return a response that dictates the AI character’s actions and dialogue. This architecture essentially turns the game into a real-time bridge between the end-user and a massive, cloud-based neural network. While this allows for unprecedented levels of conversational freedom and dynamic character behavior, it introduces a reliance on external API calls that are fundamentally different from the static assets found in traditional gaming.
The Hidden Costs of Real-Time Interaction
The primary challenge facing the developers at Easy Fox is the economic reality of token-based billing. When an application utilizes commercial AI APIs, usage is calculated by tokens—the units of text processed by the model. Every sentence typed by the player and every reactive line generated by the digital sister consumes a finite amount of computational resource, for which the developer is billed directly by the model provider.
As the popularity of the game’s demo surged, reaching 62,000 concurrent users, the volume of these API requests skyrocketed. Because the demo was released without an integrated monetization strategy or strict rate limiting, the studio found itself in a position where thousands of simultaneous interactions were generating massive, recurring bills. The developers revealed that maintaining the demo currently costs upwards of $1,000 per day. For a small team of four, this has necessitated the acquisition of bank loans just to keep the service operational, highlighting a critical disconnect between the scalability of software and the scalability of the infrastructure required to run it.
The Infrastructure Burden of Large Language Models
The situation with Teach My Little Sister How To Drive serves as a case study for the “tokenpocalypse” currently affecting developers who integrate generative AI into consumer products. In a traditional gaming model, once a game is developed, the cost of distribution is minimal, and the computational load rests on the end-user’s hardware. With cloud-based AI, the developer retains the financial responsibility for every second of gameplay.
This creates a paradox of success. Typically, a massive influx of players is a positive metric for a studio. In this instance, it functions as a financial liability. As the model providers increase their own operating costs and adjust their pricing tiers to reflect the scarcity of high-end GPU compute, developers are finding that their margins disappear. If a user spends five minutes playing the demo, the cost of the tokens generated during those five minutes may exceed the profit a developer would make from a standard one-time purchase of a game. This forces developers to consider either radical cost-cutting measures, such as switching to smaller, less capable models, or shifting the financial burden onto the consumer through subscriptions or per-interaction fees.
Reimagining Classic Gameplay Through Modern Constraints
Interestingly, the intent behind this project is to revive the experience of interactive, voice-controlled, or text-heavy simulation games that were popular in previous decades. Games like the experimental “Lifeline” or the surreal, voice-interactive “Hey You, Pikachu!” attempted to create the illusion of a reactive partner long before the advent of modern LLMs. While those early titles relied on keyword recognition and basic logic gates, Teach My Little Sister uses contemporary AI to achieve that same goal with much higher complexity.
However, the modern reliance on cloud-hosted intelligence creates a fragility that older, locally-run software did not face. In the past, once a game disc was pressed, the game’s functionality was locked and permanent. Today, the lifespan of this driving simulator is tethered to the financial solvency of the developers and their relationship with third-party cloud providers. If the studio runs out of funds, the character effectively ceases to exist, as the “brain” of the game is hosted on servers they do not own and cannot operate independently.
The Sustainability of AI-Driven Business Models
The plight of Easy Fox highlights a broader, industry-wide uncertainty regarding the profitability of generative AI. While the tech is frequently showcased in marketing for its visual flair or efficiency in asset creation, its application in real-time, consumer-facing software remains financially unproven. The costs required to support continuous, persistent AI agents are currently outpacing the willingness of the public to pay for such services.
As the industry moves forward, the trend suggests a move toward locally-run, distilled models that do not require continuous cloud interaction. For developers, the goal is to decouple the game experience from the per-token cost of external APIs. Until that transition occurs, independent studios will continue to struggle with the volatility of infrastructure expenses. Teach My Little Sister serves as a cautionary tale: the ability to generate a responsive, lifelike companion is technologically feasible, but the economic architecture to support that companion at scale remains a work in progress. Whether through lower-cost hardware solutions or more efficient model deployment, developers must find a way to stabilize these costs to avoid the threat of total service failure.
Disclaimer: This content is auto-generated for informational purposes only.
Source: Read Original News