Unlocking Hidden Computational Potential in NVIDIA Consumer GPUs
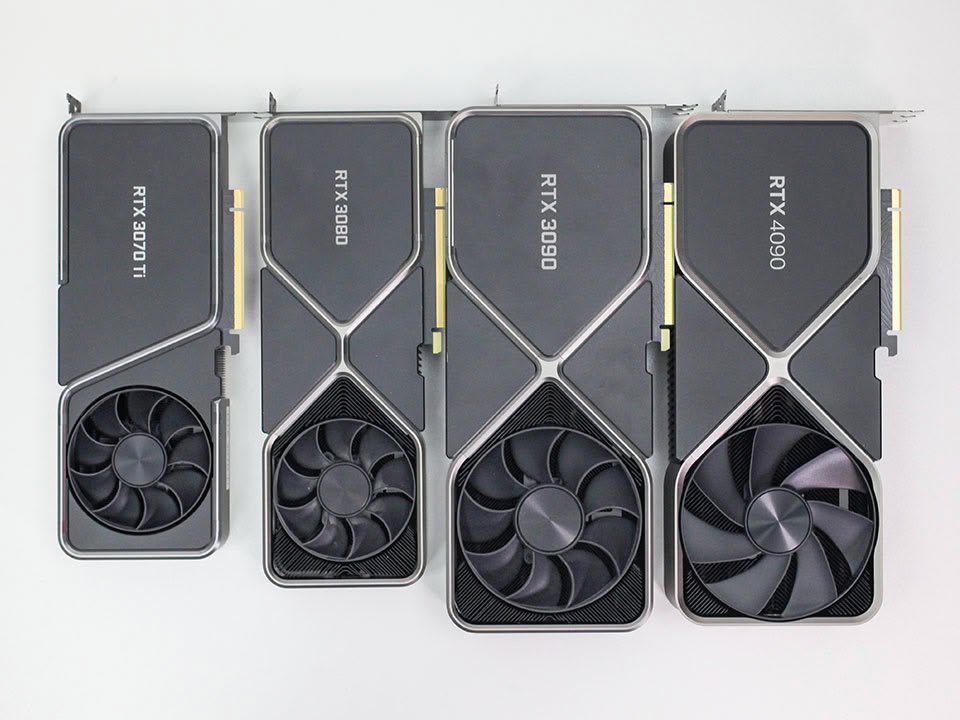
For years, the distinction between NVIDIA’s consumer-oriented GeForce lineup and their professional-grade data center hardware has been defined by more than just physical silicon and memory capacity. While both lines often share the same underlying architecture and die configurations, NVIDIA historically restricted the compute performance of consumer cards through firmware-level gatekeeping. Recently, however, researchers have successfully developed software-based modifications that bypass these constraints, effectively unlocking massive increases in computational throughput for GeForce RTX 20, 30, and 40-series cards.
These modifications target the instruction issuing rates of floating-point and bfloat16 operations, which are the fundamental building blocks of modern deep learning and artificial intelligence tasks. By overriding the limitations imposed by NVIDIA’s proprietary firmware, these researchers have demonstrated that the hardware’s actual capability is significantly higher than what is available through standard, factory-shipped configurations.
Technical Mechanisms of the Firmware Bypass
The core of this breakthrough lies in the ability to modify the instruction issuing rate for FP/BF16 FMA (Fused Multiply-Add) operations into FP32 accumulators. On standard GeForce cards, NVIDIA artificially throttles these specific operations to delineate consumer hardware from the professional-grade RTX series, such as the RTX 6000 Ada Lovelace.
The process involves an intervention that occurs at the boot sequence level. By binding the modification before the NVIDIA kernel driver initializes the graphics card, the patch successfully intercepts the firmware’s instruction limitations. Remarkably, this process is compatible with standard NVIDIA drivers and maintains the original Total Graphics Power (TGP) settings. For example, a card like the RTX 4090 maintains its 450W power envelope even after the unlock, proving that the hardware is inherently capable of this performance without requiring additional power overhead or physical voltage modifications. The unlock also successfully overrides PCIe Function Level Reset (FLR), allowing the card to remain stable during intensive compute sessions.
Performance Gains in Ampere and Ada Lovelace Architectures
The results of these modifications are profound. On the Ampere-based RTX 30-series, researchers observed an 80% improvement in matrix multiplication speeds when using BF16. Given that BF16 is the standard precision for many contemporary neural network architectures, this improvement directly correlates to faster model training and inference.
The Ada Lovelace series, specifically the flagship AD102 die found in the RTX 4090, saw even more dramatic results. Testing indicated that the stock RTX 4090 performs at roughly 165.6 TeraFLOPS in FP16 tensor throughput. Once the unlock is applied, that figure climbs to 331.6 TeraFLOPS—effectively doubling the raw computational output. This performance trajectory brings consumer-grade hardware into the same operational bracket as specialized professional hardware, which traditionally retails at a massive price premium. The update has now been extended to the Turing-based RTX 20-series, showing consistent 2x performance increases across nearly every modern NVIDIA generation.
Impact on Large Language Models and Local AI
The primary beneficiaries of these unlocks are users who engage in heavy compute-intensive tasks, particularly those running local Large Language Models (LLMs) or complex deep learning workloads. The bottleneck for many local AI tasks is the token throughput—the speed at which the model can generate or “decode” text.
By unlocking the full potential of the tensor cores, the modification significantly reduces the time required for prefill (the initial processing of a prompt) and decode (the generation of the response). For a researcher or developer running an LLM on a desktop workstation, this upgrade effectively turns a high-end gaming GPU into a high-performance compute engine capable of handling larger models with greater efficiency. It mitigates the need to invest in enterprise-grade hardware simply to achieve the throughput necessary for practical AI development in a local environment.
Implementation Risks and Practical Considerations
While the performance gains are objectively substantial, they do not come without risk. Modifying the firmware and kernel-level interaction of a GPU is a non-standard procedure that carries inherent dangers for hardware stability. Because these modifications bypass factory safety parameters intended to ensure longevity and thermal stability, users must approach this with caution.
Most importantly, modifying GPU firmware or forcing these overrides will void the product warranty. If a GPU suffers a catastrophic failure—whether related to the modification or a standard hardware defect—the manufacturer will likely deny repair or replacement. Furthermore, since these modifications must be enabled at every boot to bind before the drivers, they introduce a layer of complexity to system maintenance. Users must ensure that their software environment is compatible and that the system remains stable under the increased compute load.
The Future of GPU Compute Governance
The discovery that NVIDIA’s consumer-grade silicon possesses such significant dormant computational power raises broader questions regarding the ethics of artificial performance segmentation. While companies have legitimate reasons to create distinct product tiers, the practice of artificially crippling hardware at the firmware level creates a clear gap between the technical reality of the silicon and the user’s experience.
As the community continues to refine these software-based unlocks, it is likely that more efficient and easier-to-apply methods will emerge. This democratization of high-performance compute power may force a shift in how hardware manufacturers approach product segmentation in the future. For now, however, the ability to double the compute output of one’s existing hardware represents a milestone in technical liberty, allowing enthusiasts and professionals to push the absolute limits of their equipment for AI-driven workflows.
Disclaimer: This content is auto-generated for informational purposes only.
Source: Read Original News